Personal Language Corpus
A small corpus built from my own transcripts and exports, with provenance attached so an observation can be traced back to the passage behind it.
Independent development. Python importers, provenance and analysis workflow.
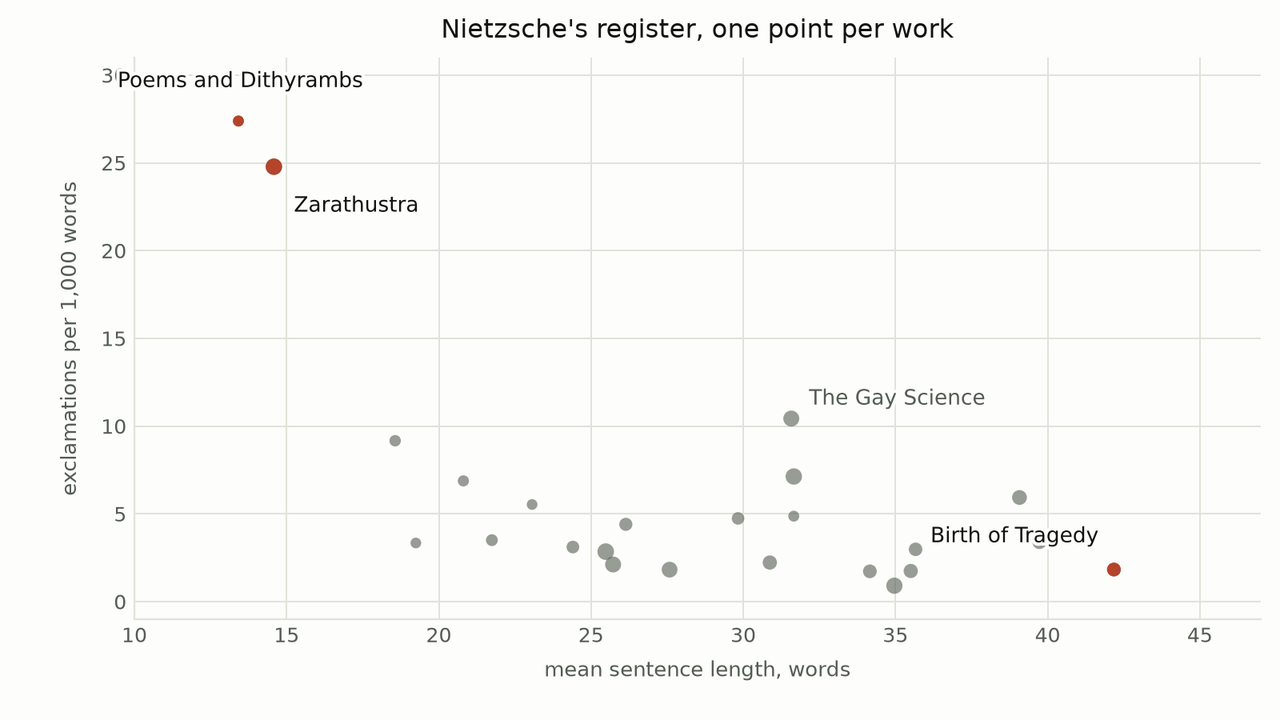
Stable passage IDs and source information survive the import, which means features and observations can point at the same text later, and the importer, the quantitative features, the baseline comparison and the qualitative pass all read from that same record.
Sample inputs are in the repo, so it runs without anyone's private data. It's mostly a way of keeping myself honest about where a claim came from.
State
A local, testable workflow that keeps the passages inspectable.